You have probably clicked a link on Wikipedia and ended up in a rabbit hole of related topics. You started reading about the Roman Empire, then clicked a link to "Julius Caesar," then one to "Assassination," and suddenly you are three hours deep into a page about the Ides of March. This isn't an accident. It is the result of a massive, invisible architecture designed to keep billions of words from turning into chaos.
Most people think Wikipedia is just a giant text file where anyone can type anything. But that would be like saying the Library of Congress is just a pile of books. The real magic lies in how the platform sorts information so you can actually find it. Two specific tools do the heavy lifting here: Categories and Portals. They work together to turn a flat database into a navigable map of human knowledge.
The Difference Between Categories and Portals
It is easy to confuse these two because they both help you navigate. But they serve completely different jobs. Think of Categories as the filing cabinets in a library's back office. They are strict, hierarchical, and automated. Every article must belong to at least one category. If you write an article about "Photosynthesis," it automatically gets filed under "Botany," "Plant Physiology," and "Cellular Processes." You don't choose this manually every time; the system uses templates to place articles based on their content.
Portals, on the other hand, are the curated display windows at the front of the store. A Portal for "Science" doesn't just list every science article. It highlights featured articles, shows current news, lists recent changes, and offers a guided tour. Portals are maintained by humans who decide what looks interesting or important today. Categories are for machines and search engines; Portals are for readers who want context.
| Feature | Categories | Portals |
|---|---|---|
| Purpose | Taxonomy and classification | Curation and discovery |
| Maintenance | Automated via templates/bots | Manual editing by users |
| Structure | Hierarchical tree (Parent/Child) | Flat or loosely grouped sections |
| User Experience | Hidden footer links, search filters | Dedicated landing pages with visuals |
| Example | Category:American_Biologists | Portal:Biology |
How Category Trees Work
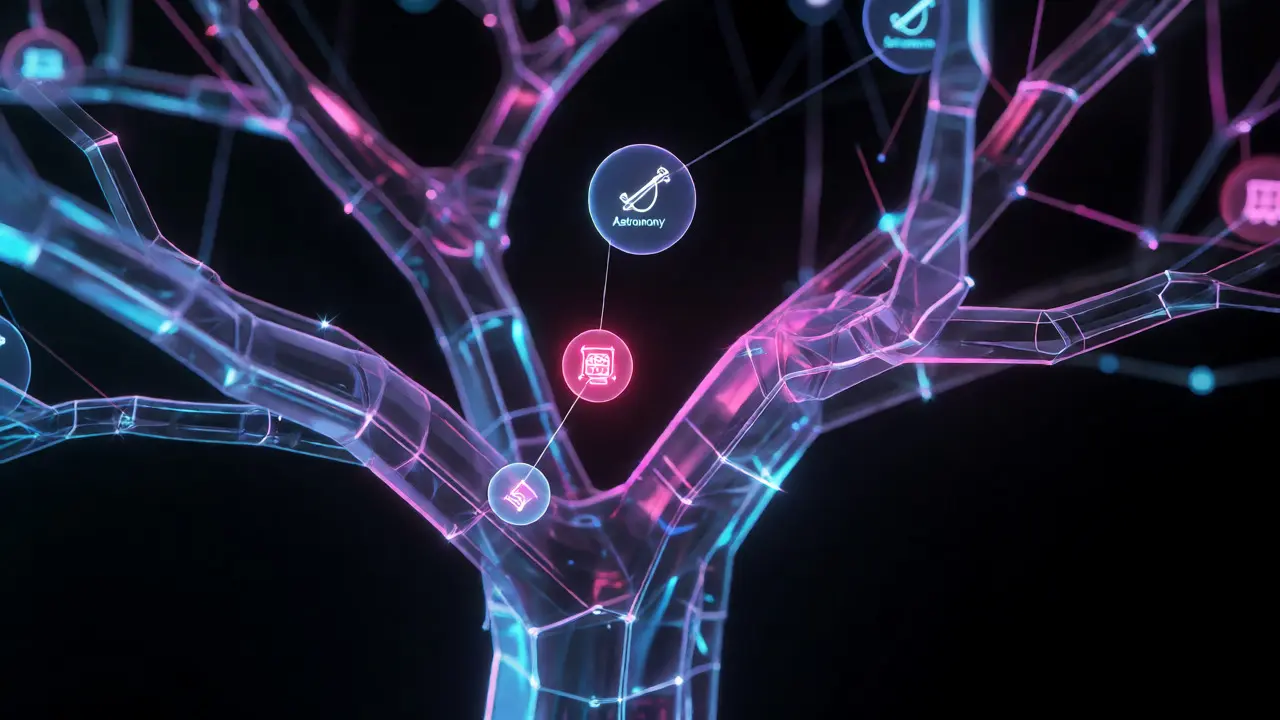
Wikipedia’s categorization system is built on a principle called transitivity. This sounds technical, but it is simple in practice. If Article A is in Category B, and Category B is in Category C, then Article A is effectively part of Category C. Let’s look at a real example. Imagine an article about the Hubble Space Telescope. It belongs to the category Astronomical observatories. That category belongs to Astronomy, which belongs to Science.
This structure allows the MediaWiki software-the engine running Wikipedia-to generate dynamic lists. When you view the category page for "Astronomy," you don't see every single astronomy article ever written. That would be millions of entries. Instead, you see subcategories. You click "Observatories," then "Space Telescopes," and finally, you find Hubble. This drill-down approach keeps the interface clean. Without this hierarchy, searching for "telescope" would return a mess of results including optical telescopes, radio telescopes, and even telescope-shaped cookies.
Editors use special code called Templates to manage this. Instead of typing out ten different category tags for a biography, an editor adds a single template like {{Infobox person}}. The template automatically assigns the correct categories for birth year, occupation, and nationality. This ensures consistency. If the rules change-say, we decide all biographers should also be categorized under "Historians"-developers update the template once, and millions of articles update instantly.
Portals as Human-Curated Hubs
If categories are the skeleton, Portals are the skin and muscle. They make the site feel alive. There are over 1,400 active portals on the English Wikipedia. Each one is a project run by a small team of dedicated editors. These editors spend hours selecting images, writing blurbs, and linking to breaking news.
Take the Portal:Current events. It is not just a list of dates. It aggregates news from around the world, links to relevant background articles, and provides a timeline. If a major earthquake hits Japan, the portal updates within minutes. It links to the main article on the quake, but also to articles on Japanese geology, previous earthquakes in the region, and emergency response protocols. This contextual layering helps readers understand *why* an event matters, not just *what* happened.
Portals also solve the problem of "orphaned" content. Some niche topics, like "Medieval Alchemy," might have great articles but no obvious way for a casual reader to stumble upon them. The Portal:Chemistry or Portal:History can feature these articles in a "Did you know..." section. This boosts visibility for content that search algorithms might miss because few people explicitly search for those terms.
The Role of Disambiguation Pages
Before an article even reaches a category, it often has to pass through a Disambiguation Page. This is a critical filter in the organizational flow. Words are messy. "Apple" could mean the fruit, the tech company, or the record label. If you search for Apple, Wikipedia cannot guess your intent. So, it sends you to a disambiguation page that lists all options.
These pages are organized logically. Usually, the most common meaning comes first. For "Apple," the tech company likely appears before the fruit due to search volume trends. Each entry on the disambiguation page links directly to the specific article. This step ensures that when you finally land on the correct article, it carries the right metadata. The article for "Apple Inc." will never be mixed into the "Fruits" category. This precision prevents data pollution in the category trees.
Why This Structure Matters for Search
You might wonder why you should care about internal Wikipedia mechanics if you just want to read. Here is the thing: Google and other search engines crawl these structures heavily. When you search for "famous physicists," Google looks at Wikipedia’s category trees to determine relevance. Because Physicists is a well-defined category with clear parent nodes like "Scientists" and "Academics," search engines trust these associations.
Furthermore, the Wikidata integration relies on this organization. Wikidata is a sister project that stores structured data. It connects Wikipedia articles to unique identifiers. When you ask Siri or Alexa about a historical figure, they pull data from Wikidata, which is linked to Wikipedia via these categorical and portal structures. Poorly organized categories lead to poor data extraction. If an article is miscategorized, the AI assistant might give you wrong facts.
Common Pitfalls in Organization
Despite the robust system, things break. One common issue is "over-categorization." An editor might tag an article about a minor local politician with broad categories like "Politics" and "Government." While technically true, it clutters the top-level views. Wikipedia guidelines encourage specificity. Instead of just "Politics," use "Politicians from Madison, Wisconsin." This makes the category useful for someone researching local history, rather than useless for someone looking for national leaders.
Another pitfall is "circular references." Sometimes, Category A says it contains Category B, but Category B claims to contain Category A. This creates a loop that bots struggle to resolve. Editors have to manually fix these logic errors. It is tedious work, but necessary. Without it, the navigation tree becomes infinite, and users get stuck clicking between two identical-looking pages.
Practical Tips for Navigators
If you want to master Wikipedia’s organization, stop using the search bar immediately. Try starting with a Portal. If you are interested in space, go to Portal:Astronomy. Browse the "Featured Articles" section. These are vetted for quality and readability. Then, use the "Related Portals" sidebar to jump to adjacent fields like Physics or Engineering.
When you find an article, scroll to the bottom. Look at the categories listed there. Click on the most specific one. This is often the best way to discover similar topics. If you are reading about a specific war, the category "Conflicts in [Year]" will show you all other wars happening at the same time. This lateral movement is faster than sequential reading.
Finally, check the "What Links Here" tool in the left-hand menu. It shows every page that points to the current article. This reveals the community’s perspective on the topic. If many high-profile portals link to your article, it is considered central to that field. If only obscure footnotes link to it, it is peripheral.
Frequently Asked Questions
Can I add my own category to an article?
Yes, but you must follow strict guidelines. You cannot create a new category unless it serves a distinct purpose that existing categories do not cover. You also need to ensure the category fits into the existing hierarchy. If you add a random category without a parent, it may be deleted by administrators during routine maintenance sweeps.
Do Portals affect search rankings outside of Wikipedia?
Indirectly, yes. Search engines value well-structured sites. High-quality portals signal authority and topical depth. If your article is featured in a popular portal, it gains more internal links and user engagement metrics, which can boost its visibility in external search results like Google.
What happens if an article has no categories?
It becomes an "uncategorized page." These are flagged for cleanup. Uncategorized articles are hard to find via browsing and may be overlooked by bots and humans alike. Editors prioritize adding categories to these pages to integrate them into the wider network of knowledge.
Are Wikipedia Categories permanent?
No. Categories evolve as language and society change. A category like "Ladies' Rights" might be renamed to "Women's Rights" to reflect modern terminology. Mergers and splits happen frequently. Always check the discussion tab on a category page to see if there are ongoing debates about its definition or scope.
How many categories does a typical article have?
It varies widely. A short stub might have 1-2 categories. A comprehensive article on World War II could have 50 or more, spanning military history, politics, economics, and geography. The goal is accuracy, not quantity. Redundant categories are usually removed to keep the metadata clean.